3 min readGuide
Metrics for LLMs, RAG and Cybersecurity Systems
LLM and RAG metrics: retrieval recall, citations, unsafe actions, calibration, latency and uncertainty. Define fair comparisons.
Research notes and technical guides on federated learning, distributed AI, cyberdefense, trustworthy systems, and privacy-preserving platforms.
30 articles. Page 3 of 5.
3 min readGuide
LLM and RAG metrics: retrieval recall, citations, unsafe actions, calibration, latency and uncertainty. Define fair comparisons.
5 min readResearch note
Compare models and prototypes in DFL: message size, cumulative bytes, quantization and target quality under network constraints.
5 min readResearch note
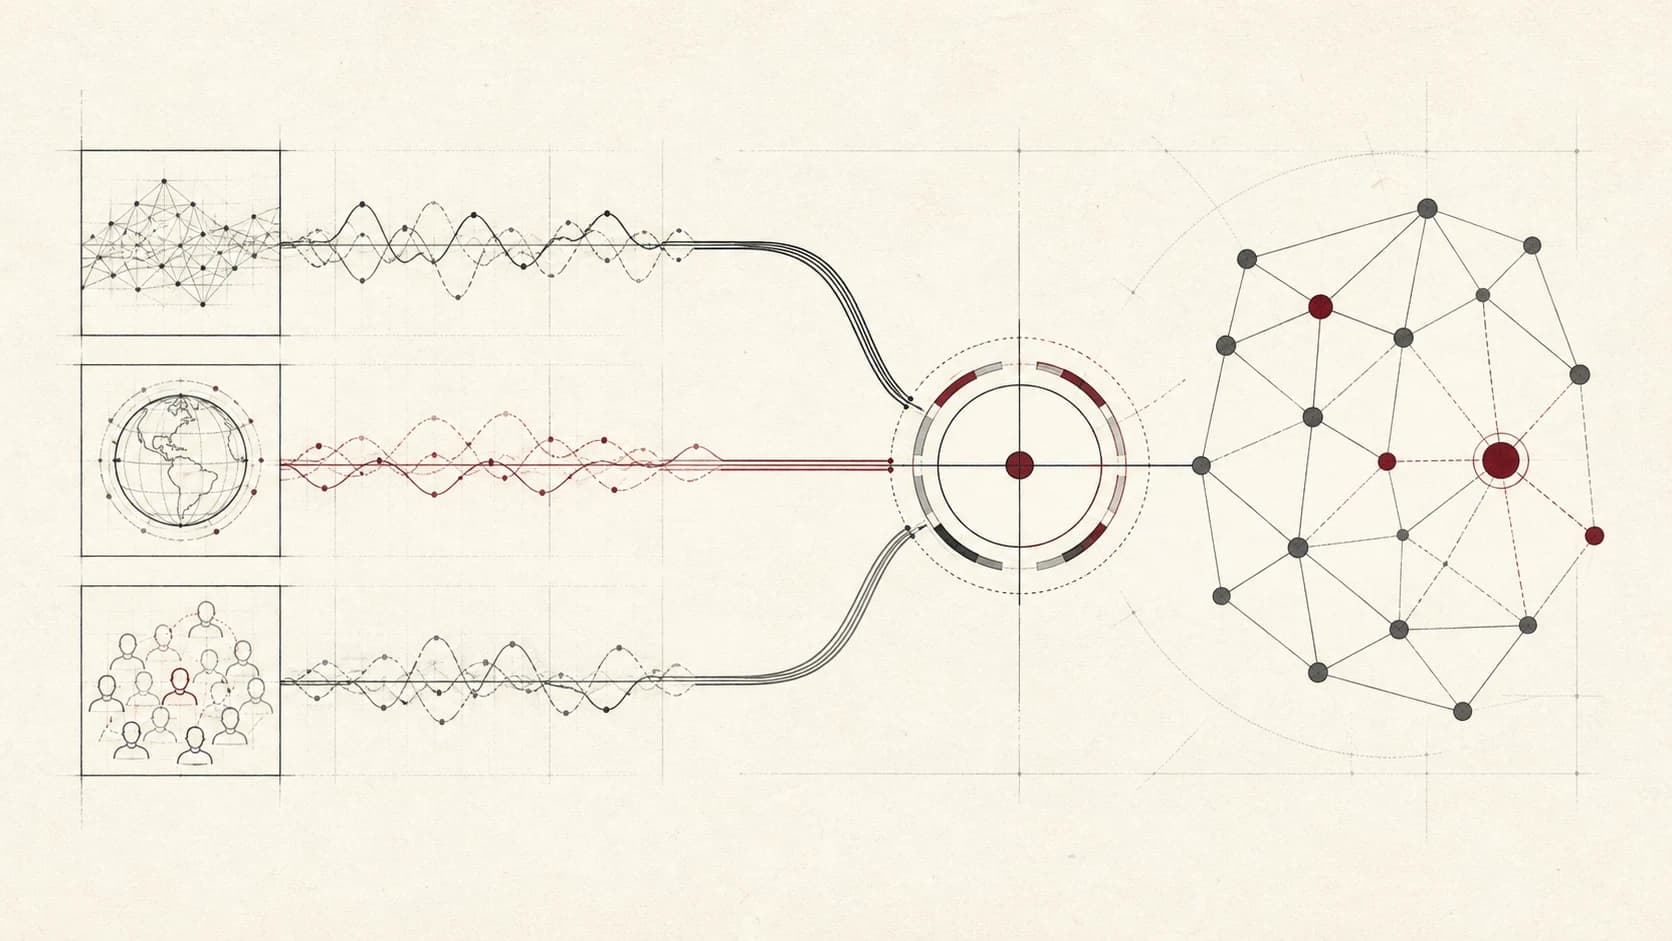
How Modalis works: multimodal prototypes, gating and alignment in DFL. Published results, limitations and proposed ablations.
5 min readResearch note
Multimodal federated learning with non-IID data and missing sensors: masks, prototypes and evaluation by modality and client.
5 min readResearch note
Evaluate DFL robustness with F1, false rejection, overhead and recovery. Interpret Flighter and compare clean and attacked conditions.
5 min readResearch note
How Flighter combines context and models to evaluate DFL reliability: study scope, indicator ablations and participant recovery.
This site loads optional analytics from Google and external analytics providers only if you accept. You can decline and continue using the site normally.