3 min readGuide
Golden Sets for LLM Evaluation: Small, Curated and Difficult to Cheat
Build golden sets for LLMs and RAG with examples, adjudication, leakage-aware splits and bilingual security cases.
Research notes and technical guides on federated learning, distributed AI, cyberdefense, trustworthy systems, and privacy-preserving platforms.
13 articles. Page 2 of 3.
3 min readGuide
Build golden sets for LLMs and RAG with examples, adjudication, leakage-aware splits and bilingual security cases.
3 min readGuide
LLM and RAG metrics: retrieval recall, citations, unsafe actions, calibration, latency and uncertainty. Define fair comparisons.
5 min readGuide
Design a DFL system with topology, message contracts, mixing weights, recovery policies and per-client evaluation.
5 min readGuide
From the DFL survey to Flighter and Modalis: turn literature into testable hypotheses, reproducible experiments and traceable evidence.
5 min readGuide
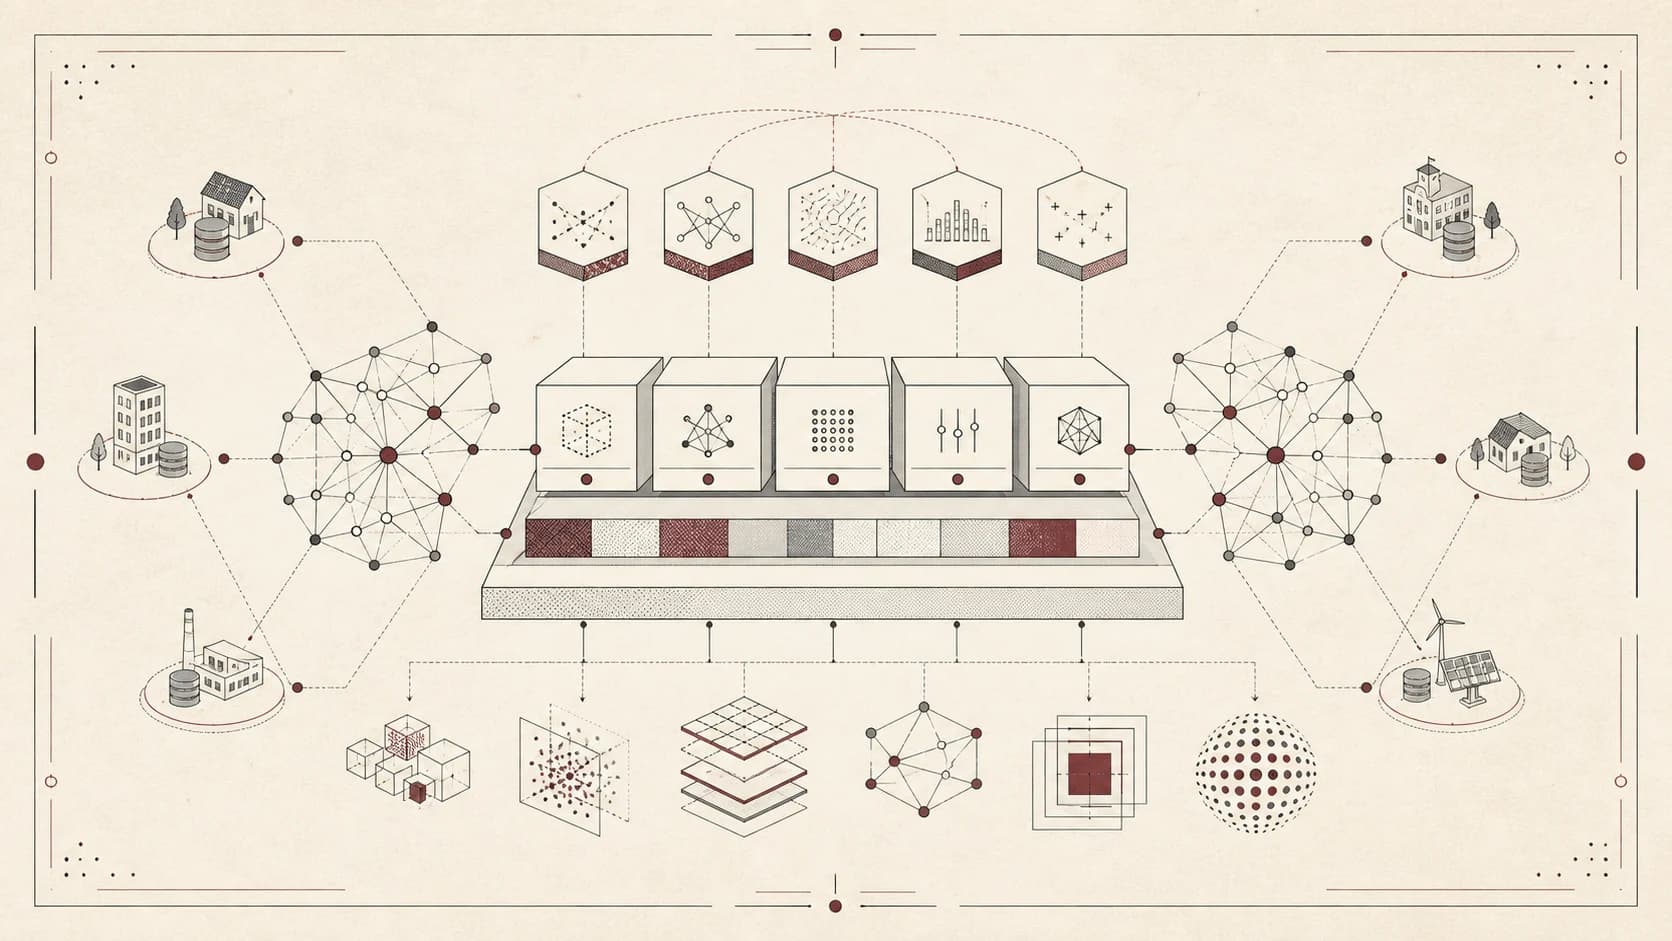
NEBULA guide: architecture, official documentation and a reproducible protocol for evaluating DFL topology, privacy, attacks and resources.
7 min readGuide
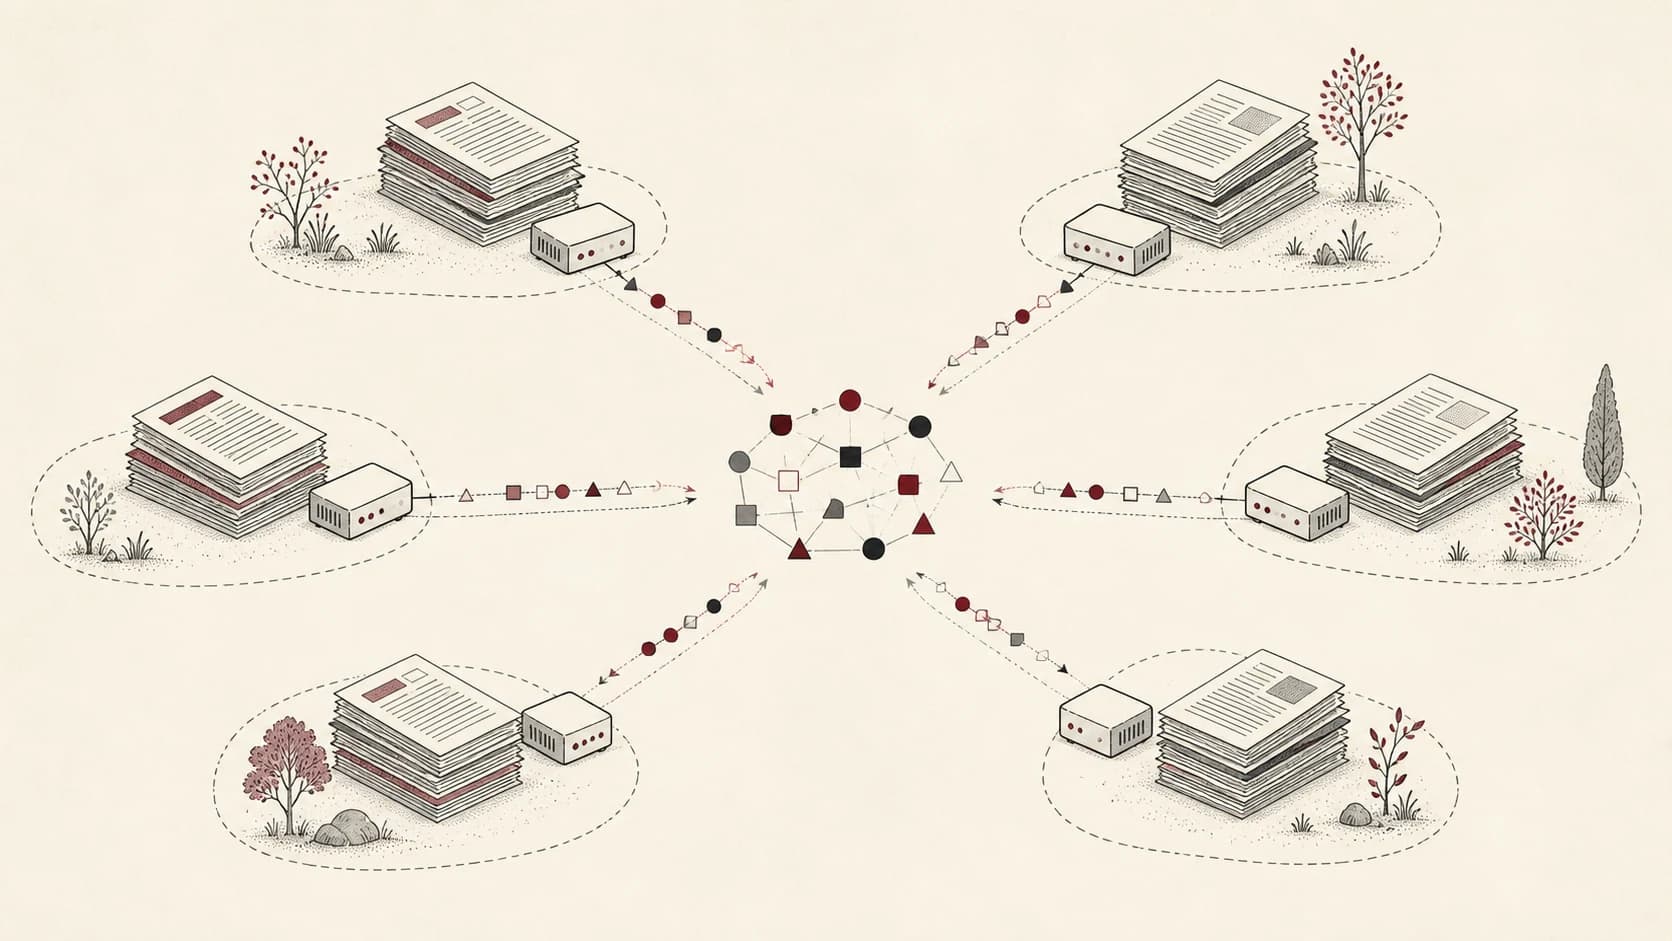
Learn how federated learning and FedAvg work, what differential privacy and secure aggregation protect, and how to evaluate collaboration.
This site loads optional analytics from Google and external analytics providers only if you accept. You can decline and continue using the site normally.