3 min readGuide
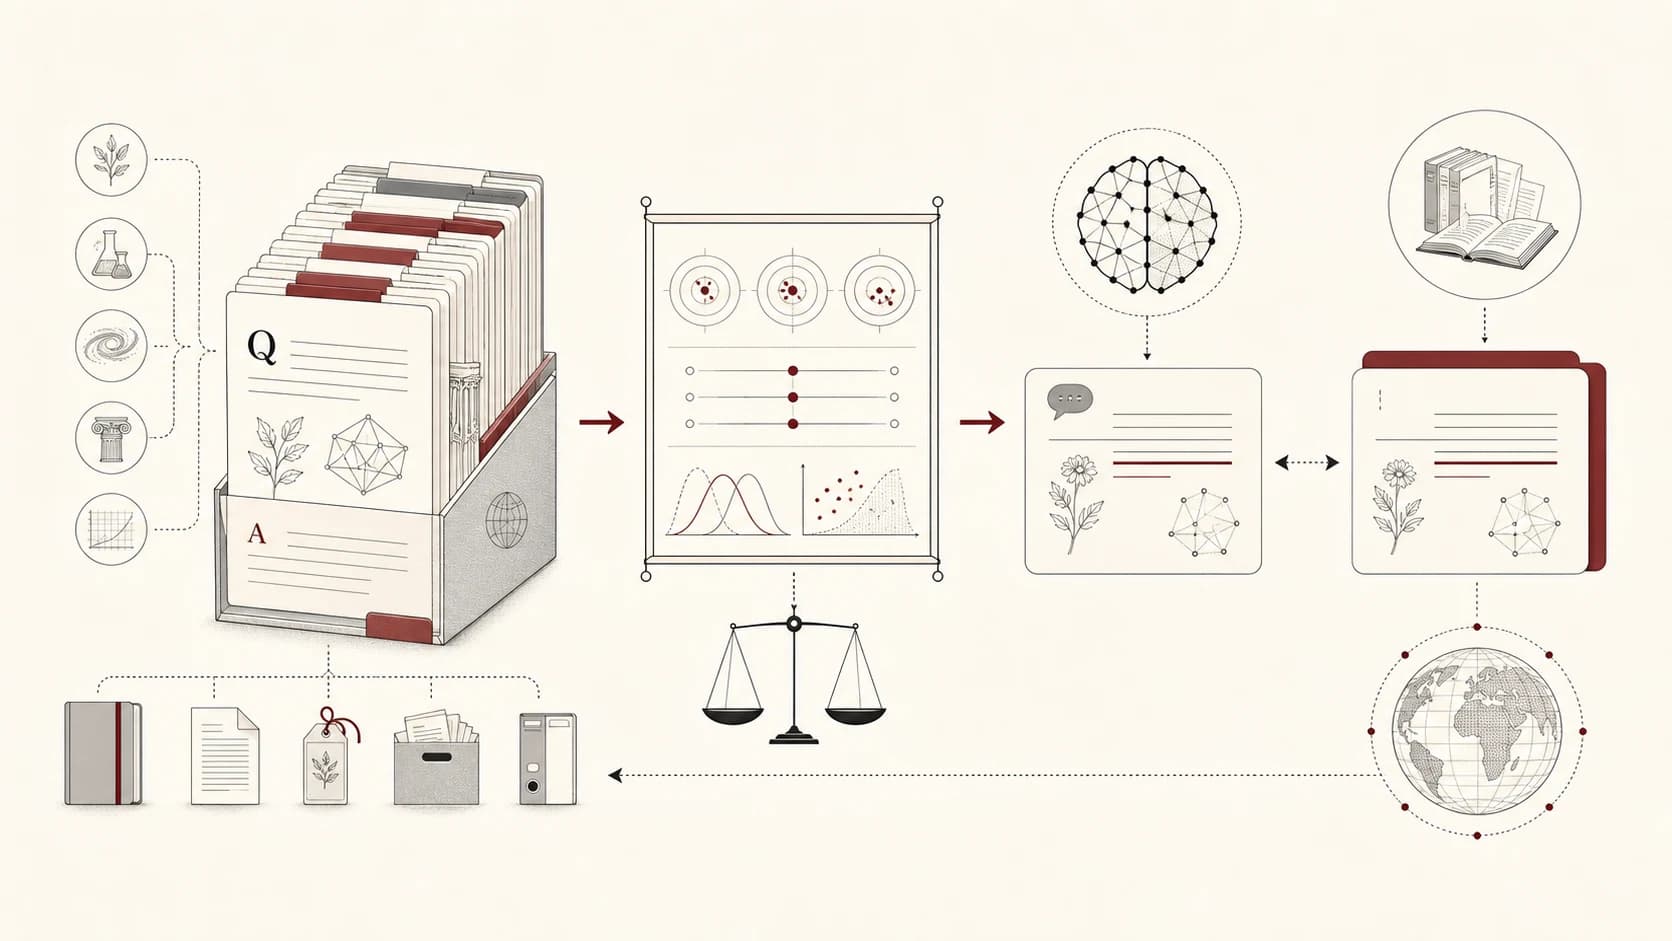
Golden Sets for LLM Evaluation: Small, Curated and Difficult to Cheat
Build golden sets for LLMs and RAG with examples, adjudication, leakage-aware splits and bilingual security cases.
Research notes and technical guides on federated learning, distributed AI, cyberdefense, trustworthy systems, and privacy-preserving platforms.
Topic: LLMs for Cyberdefense Support Clear topic
17 articles. Page 2 of 3.
3 min readGuide
Build golden sets for LLMs and RAG with examples, adjudication, leakage-aware splits and bilingual security cases.
3 min readGuide
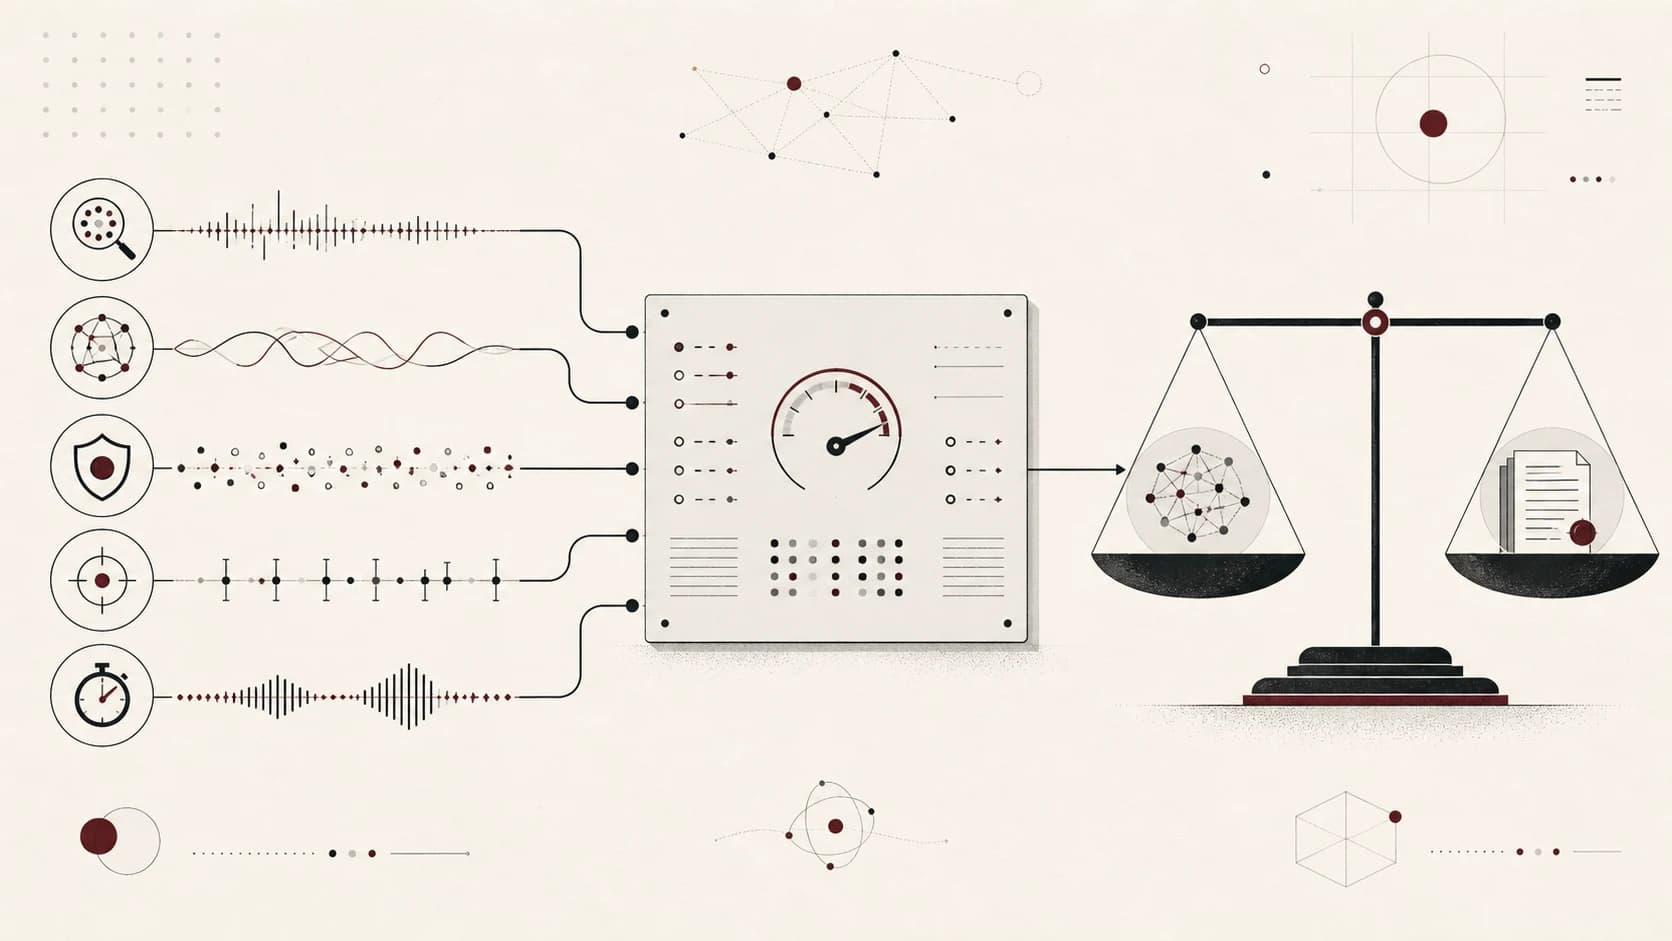
LLM and RAG metrics: retrieval recall, citations, unsafe actions, calibration, latency and uncertainty. Define fair comparisons.
5 min readResearch note
Evaluate DFL robustness with F1, false rejection, overhead and recovery. Interpret Flighter and compare clean and attacked conditions.
5 min readResearch note
How Flighter combines context and models to evaluate DFL reliability: study scope, indicator ablations and participant recovery.
5 min readGuide
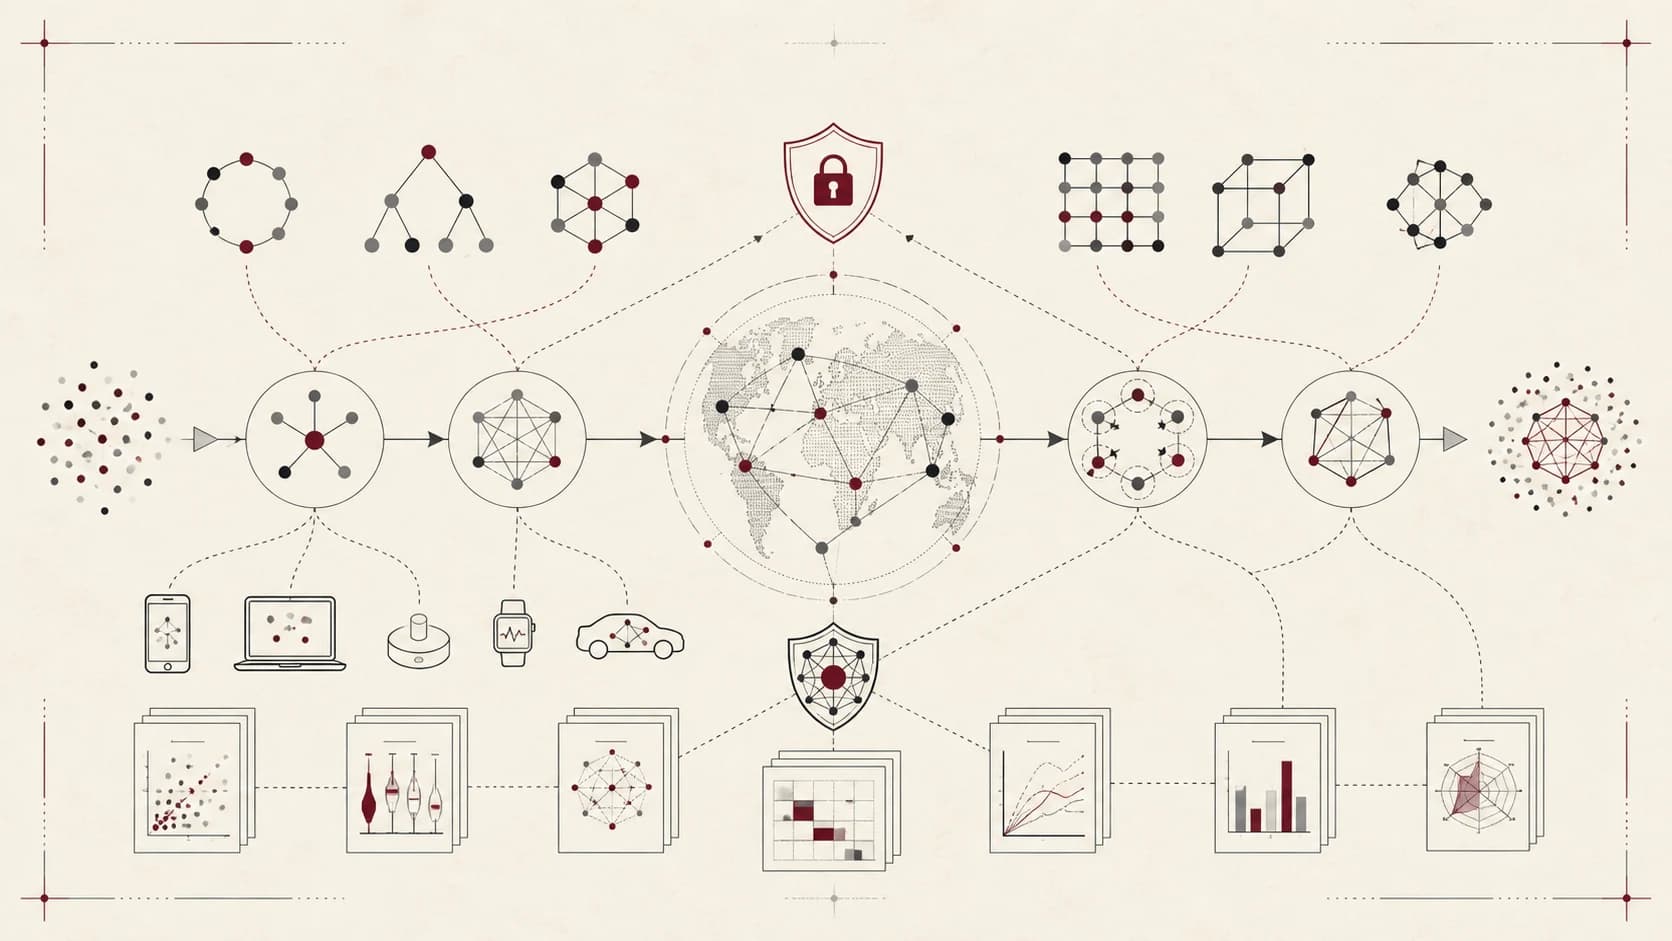
From the DFL survey to Flighter and Modalis: turn literature into testable hypotheses, reproducible experiments and traceable evidence.
5 min readResearch note
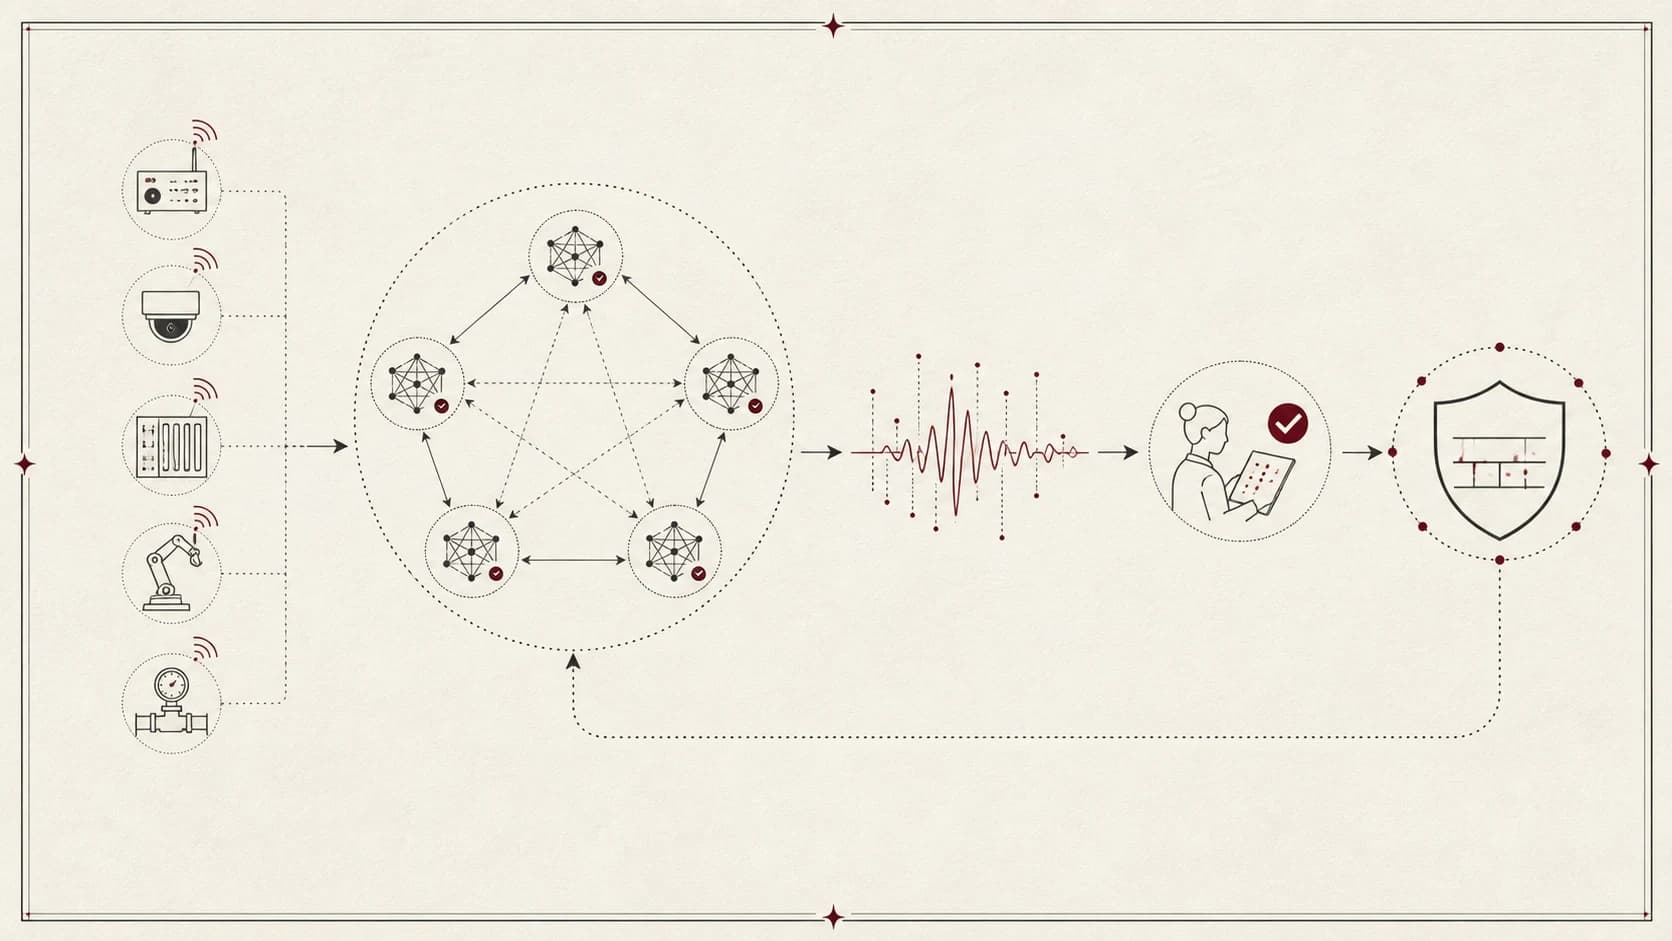
Connect telemetry, federated learning, alerts and LLM-assisted mitigation with traceable evidence, validation and reviewed feedback.
This site loads optional analytics from Google and external analytics providers only if you accept. You can decline and continue using the site normally.